Deploying an AI inference API in 2026 is not a weekend side project anymore. It is a production decision that affects latency, uptime, and monthly infrastructure bills all at once. Global spending on AI inference infrastructure is projected to reach roughly 117.80 billion dollars in 2026, and that number keeps climbing every quarter as more companies push large language models and computer vision pipelines into live production. Yet most teams still get stuck on one basic question before any of that spending even begins: VPS vs Dedicated, and which one should actually host the inference workload.
This guide breaks the VPS vs Dedicated decision down layer by layer, specifically for AI inference of APIs, not generic web apps. It explains where a VPS genuinely works for inference, where a dedicated server becomes unavoidable, and how Indian businesses should plan a 2026 rollout that does not blow the budget. The comparison looks different for inference workloads than it does for a blog or a CRM, because inference is compute-hungry, latency-sensitive, and often GPU-bound.
For businesses that already run a model in a notebook and now need to serve it through an API, the real question in 2026 is not whether to host it in the cloud. It is which side of the VPS vs Dedicated line the workload belongs on, because picking wrong here is one of the most expensive infrastructures mistakes a growing AI product can make. Whichever path fits, the right Web Hosting Company in India can make the transition considerably smoother.
Table of Contents
- What Is the Core Question, Really?
- Why This Decision Matters More for Inference in 2026
- Breaking Down VPS for AI Inference APIs
- Breaking Down Dedicated Servers for AI Inference APIs
- Performance Benchmarks for Real Inference Workloads
- How to Choose the Right Option for Your Inference API
- Cost Planning Across Both Options
- Infrastructure Readiness for Inference Deployment
- This Decision for Small and Mid-Sized AI Teams in India
- Common Mistakes That Undermine an Inference Deployment
- Security, Compliance, and DPDPA 2023 Considerations
- Customised Hosting Plans by AI Team Size
- Measuring Success Beyond Launch
- Choosing the Right Infrastructure Partner
- Matching Hosting Options to Your Inference Path
- Conclusion
- Key Takeaways
- Frequently Asked Questions
1. What Is the VPS vs Dedicated Question, really?
The VPS vs Dedicated question is really a question about resource isolation, and for AI inference APIs that isolation decides whether your response times stay predictable under load.
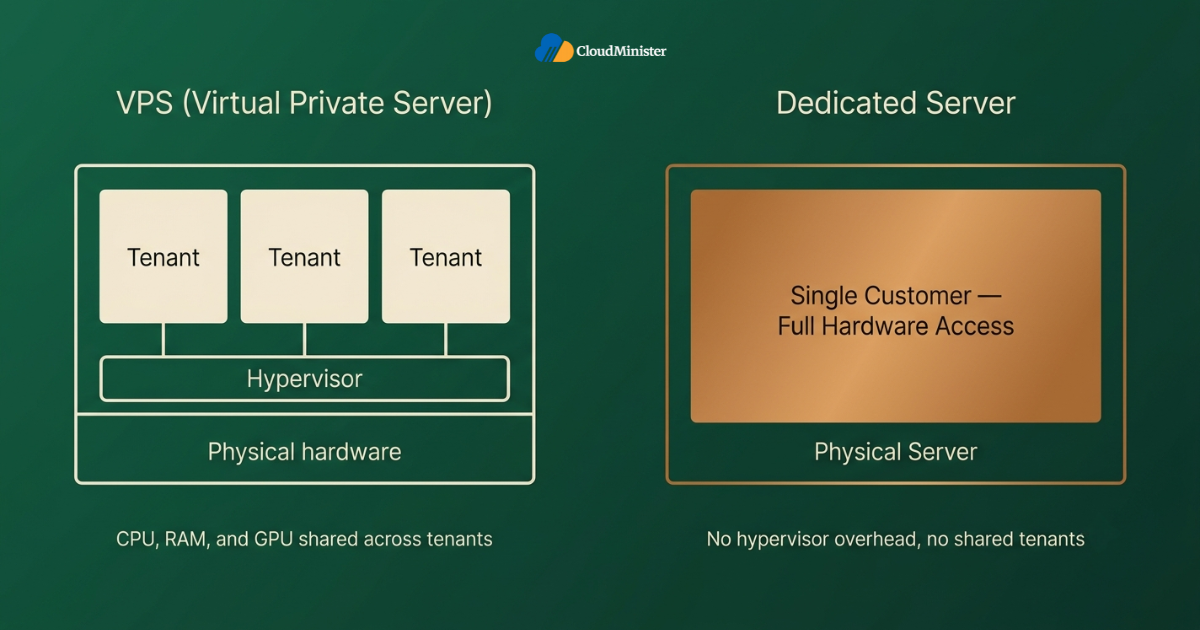
- A VPS (Virtual Private Server) is a slice of a larger physical machine, partitioned using a hypervisor, where CPU, RAM, and sometimes GPU resources are shared with other tenants on the same host.
- A Dedicated Server is an entire physical machine allocated to one customer, with no hypervisor overhead and no other tenant competing for the same CPU cache, memory bandwidth, or GPU.
- In this comparison, the core technical difference is not “how much RAM you get” — it is whether your inference process shares silicon with a stranger’s workload.
- For inference APIs specifically, this matters more than for most other workloads because model inference is bursty: idle for milliseconds, then a spike of matrix multiplications the moment a request lands.
- The framework forces teams to evaluate the workload honestly instead of defaulting to whatever they already know from web hosting, and a knowledgeable Web Hosting Company in India can help walk through that evaluation.
Whichever side of the VPS vs Dedicated decision you land on, your inference API is a network-facing endpoint that accepts untrusted input and returns model output. Run an input-validation and rate-limiting review before going live, and confirm your hosting environment isolates your model weights and API keys properly. This matters directly for businesses handling user data under India’s Digital Personal Data Protection Act (DPDPA) 2023.
2. Why This Decision Matters More for Inference in 2026
Enterprise data shows how fast this space is moving. Inference has become the dominant AI compute workload, and industry analysts project it will represent roughly two-thirds of all AI compute usage this year, up sharply from just a third a few years ago, according to a Gartner-cited industry analysis tracking the shift toward inference as the primary consumer of AI-optimized infrastructure spending in 2026.
- 94 percent of enterprises now run some form of AI workload in production, but running a workload and hosting it correctly are two very different things.
- The VPS vs Dedicated choice is where most inference latency problems actually originate, not in the model architecture itself.
- Real-world survey data backs this up directly: 71 percent of IT leaders reported experiencing excessive latency affecting their AI workloads, while 54 percent said fiber and network availability delayed their AI deployments entirely, underscoring that the underlying infrastructure choice, not just the model, drives production performance.
- Teams that default to a VPS for every inference workload, or default to a dedicated server for every inference workload, routinely overspend or under-perform, and structured evaluation reduces this risk considerably.
- AI-specific compliance mandates, GPU shortages, and rising inference volumes are common 2026 triggers for revisiting this decision on an existing deployment.
- A clear VPS vs Dedicated evaluation framework gives engineering leaders a way to justify infrastructure spend to finance teams who are watching AI budgets closely this year.
- Consulting an experienced Web Hosting Company in India early in the planning process often surfaces constraints that internal teams miss until launch week.
Businesses comparing VPS Hosting in India providers at this stage should also ask each vendor how they handle noisy-neighbour isolation for CPU-bound inference tasks, since not every VPS plan is built the same way, and not every Fully Managed VPS Hosting tier includes the same level of proactive monitoring. Before committing to either option, run a two-week load test simulating your expected request volume, batch size, and token throughput. This single step prevents most of the expensive infrastructure mistakes teams make when scaling an inference API.
3. Breaking Down VPS for AI Inference APIs
Not every inference workload needs a dedicated server. Here is what a VPS actually offers when you put it up against a dedicated server for this specific use case.
3.1 What a VPS Brings to the Table
- A VPS gives you fast provisioning, meaning you can spin up an inference endpoint in minutes rather than waiting for physical hardware allocation.
- It is billed flexibly, usually monthly or hourly, which suits early-stage AI products that have not yet locked in stable traffic patterns.
- A VPS is well suited for small language models, lightweight classification APIs, embedding generation at modest volume, or an internal tool used by a handful of employees.
- Resource limits are clearly defined upfront (vCPU count, RAM, sometimes a shared or fractional GPU), so cost stays predictable even if performance has a ceiling.
- Many businesses evaluating a virtual server as a starting point for AI experimentation appreciate that they can resize the plan later without a hardware migration.
- A well-configured Fully Managed VPS Hosting plan removes most of the patching and monitoring overhead from a small engineering team’s plate entirely.
- Choosing Fully Managed VPS Hosting also means security patches and kernel updates happen on a predictable schedule instead of being an afterthought.
- Teams that start on Fully Managed VPS Hosting often find the support desk catches configuration issues before they ever affect production traffic.
3.2 Where a VPS Struggles With Inference
- Shared hypervisor resources mean CPU steal time is a real risk, and CPU steal time directly translates into unpredictable inference latency under concurrent load.
- Most VPS plans offer limited or shared GPU access, which becomes a hard ceiling the moment you move from a small model to anything in the multi-billion parameter range.
- Memory bandwidth is shared across tenants on the same physical host, and large transformer models are extremely memory-bandwidth-hungry during the forward pass.
- In the VPS vs Dedicated comparison, this is the exact point where a growing AI product typically hits a wall and has to migrate.
- Even a strong Fully Managed VPS Hosting provider cannot remove the physical ceiling imposed by shared hardware once a model outgrows it, and at that point Dedicated Servers in India become the more realistic path forward.
Start Your Inference API on a Fully Managed VPS
Prototyping a model or running a lightweight inference workload? Get a fast, fully managed VPS built for predictable performance without the dedicated-hardware commitment.
Related Reading: NVMe vs SSD Hosting: What Actually Changes Performance
4. Breaking Down Dedicated Servers for AI Inference APIs
On the other side of the VPS vs Dedicated equation sits the dedicated server, and for serious inference workloads it solves problems a VPS structurally cannot. Dedicated Server Hosting in India has grown considerably in 2026 as more Indian AI teams move production models off shared infrastructure. A Web Hosting Company in India that already runs GPU inventory at scale can usually turn around provisioning far faster than a generic cloud reseller.
4.1 What a Dedicated Server Brings to the Table
- Full, exclusive access to CPU cores, RAM, storage, and GPU resources means no hypervisor tax and no noisy-neighbour interference from another tenant’s workload.
- Predictable, consistent inference latency, since your process is never competing for L2/L3 cache or memory bandwidth with anyone else’s job.
- The ability to run large language models, high-throughput batch inference, or multiple concurrent model instances without hitting a shared-resource ceiling.
- Full control over the driver stack, CUDA versions, and kernel-level tuning, which matters enormously for GPU-bound inference performance optimisation on Dedicated Server Hosting in India.
- Dedicated Servers in India built for GPU workloads are the standard choice once an inference API moves from prototype to a business-critical, revenue-generating production system.
- Providers offering Dedicated Server Hosting in India with genuine hardware-level GPU access, rather than a virtualised slice, matter enormously here.
4.2 When a Dedicated Server Becomes the Clear Choice
- When your model requires a full GPU or multiple GPUs and cannot tolerate resource contention from other tenants.
- When you are running high-concurrency inference where dozens or hundreds of simultaneous requests need consistent sub-second response times.
- When compliance or data-residency requirements make hardware isolation a strong preference rather than one option among several.
- When your inference volume has grown large enough that Dedicated Server Hosting in India’s flat, predictable cost beats scaling VPS instances horizontally.
- Many teams reach this point specifically because their earlier Dedicated Servers in India research already flagged GPU contention as a coming bottleneck, prompting an early move to Dedicated Server Hosting in India before the problem became urgent.
Related Reading: Bare Metal vs Dedicated Server: Clearing Up the Confusion
Ready for Dedicated GPU Power?
When your inference workload outgrows shared resources, move to a dedicated server with full GPU access, no noisy neighbours, and consistent sub-second latency.
Teams that get the most value out of the VPS vs Dedicated decision resist the urge to pick one option and apply it to every workload in their stack. A realistic AI product architecture often runs its lightweight preprocessing or embedding service on a VPS while the actual model inference, especially anything GPU-bound, runs on a dedicated server. The right choice is workload-specific, not company-wide.
5. Performance Benchmarks: VPS vs Dedicated for Real Inference Workloads
Numbers matter more than opinions when you are deciding between these two options for a production inference API. Here is what actually changes, and where Dedicated Servers in India routinely outperform a shared instance under real traffic.
- Latency consistency: a dedicated server typically holds a tighter latency distribution (lower p95 and p99 response times) because there is no hypervisor scheduling jitter, while a VPS can show latency spikes during host-level contention.
- Throughput ceiling: a VPS with a shared or fractional GPU caps out quickly on tokens-per-second for larger models, while a dedicated server with a full GPU scales throughput close to the hardware’s rated capacity.
- Cold-start behaviour: both environments face model-loading cold starts, but Dedicated Server Hosting in India with NVMe storage and full memory bandwidth loads large model weights into memory noticeably faster.
- Cost-per-inference at scale: at low request volume, a VPS usually wins on cost-per-inference; past a certain concurrency threshold, a dedicated server’s flat pricing wins instead.
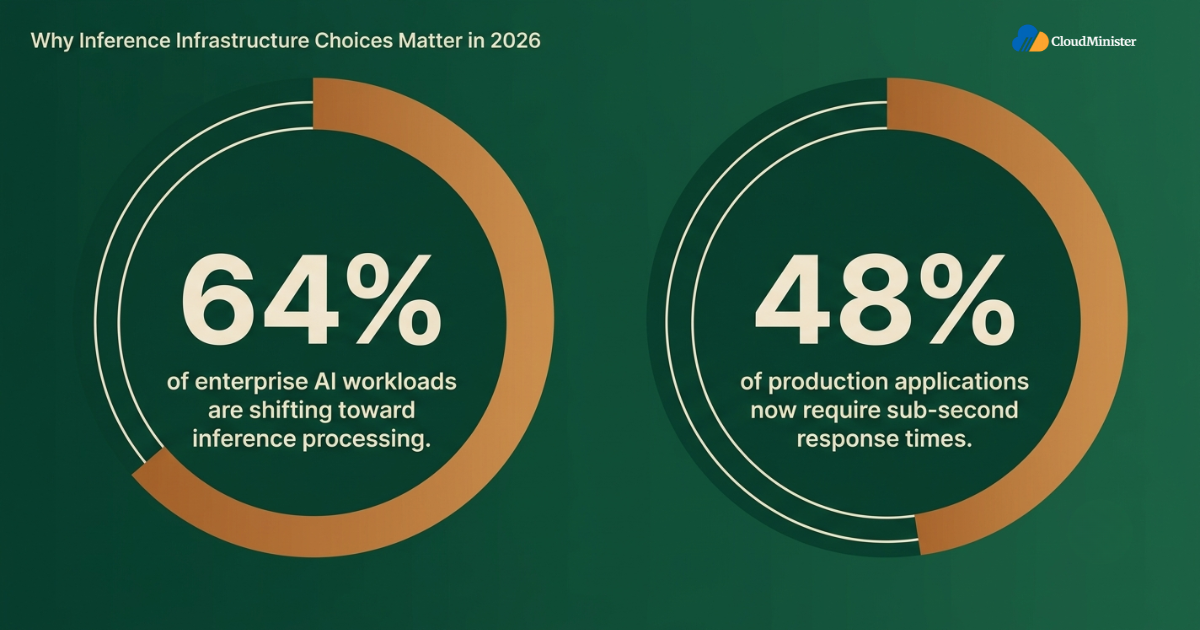
- Enterprises are already feeling this squeeze directly. Roughly 64 percent of enterprise AI workloads are shifting toward inference processing, and 48 percent of production applications now require sub-second response times, which is precisely the kind of demand that exposes the difference between shared and dedicated infrastructure.
Related Reading: VPS Hosting in India: A Full Pricing Breakdown
6. How to Choose the Right Option for Your Inference API
Choosing correctly between VPS vs Dedicated requires structured evaluation of your actual workload, not a gut call based on what other teams are using.
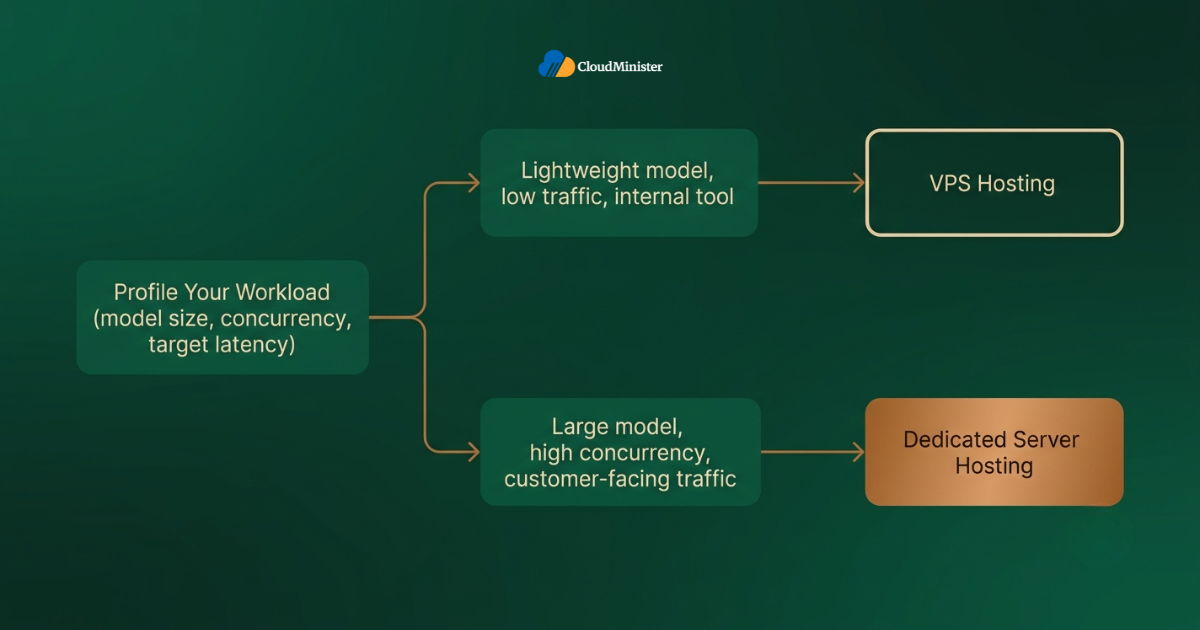
- Start by profiling your model: parameter count, batch size, expected concurrent requests, and target latency (p50, p95, p99) before mapping it to either option.
- APIs serving lightweight models, low traffic, or internal-only tools generally favour a VPS, since speed of deployment and lower upfront cost matter more than raw throughput.
- APIs serving large language models, computer vision at scale, or customer-facing production traffic typically justify the investment required for Dedicated Server Hosting in India.
- If your compliance obligations under DPDPA 2023 point toward stricter data isolation for your specific data categories, that can be one factor tipping the VPS vs Dedicated question toward dedicated hardware.
- Anything still in the prototyping or proof-of-concept phase should stay on VPS Hosting in India until real traffic patterns justify the jump to dedicated infrastructure.
- Where budget is tight, businesses can lean on Fully Managed VPS Hosting for early-stage inference work, reserving dedicated spend for the models that genuinely need it.
- A short conversation with a Web Hosting Company in India that offers both tiers can also clarify migration paths before you commit to either one.
Checklist: What to Evaluate Before Choosing VPS vs Dedicated
- Model size and GPU memory requirements
- Expected concurrent request volume and peak traffic patterns
- Target latency SLA (p50, p95, p99) for your inference API
- Data residency and compliance requirements under DPDPA 2023
- Budget ceiling and whether cost scales linearly with traffic
- Internal DevOps bandwidth available to manage dedicated infrastructure
- Whether the workload is still in prototyping or already business-critical
Related Reading: How to Choose the Right Dedicated Server
7. Cost Planning Across VPS vs Dedicated
Budgeting looks completely different depending on which side of the VPS vs Dedicated line your inference workload lands on.
- VPS Hosting in India plans typically carry the lowest upfront cost and the fastest time-to-deployment, but throughput ceilings mean costs can climb fast once you scale horizontally with more instances.
- Dedicated Server Hosting in India setups require a larger upfront or monthly commitment, but tend to produce a lower cost-per-inference once request volume crosses a meaningful threshold.
- GPU availability and pricing are volatile in 2026, and this volatility affects both options, so budget with some flexibility built in, especially for Dedicated Servers in India where GPU allocation is fixed for the contract term.
- Data transfer and API egress costs are frequently underestimated on both sides of the VPS vs Dedicated comparison, and should be modelled into the budget from day one.
- Businesses evaluating a Web Hosting Company in India should factor in not just the base hosting bill, but which option actually matches their inference volume, since that decision drives most of the total cost.
- A well-scoped Dedicated Server Hosting in India contract, negotiated alongside your expected inference growth curve, typically produces a cleaner budget than reacting to cost overruns after launch.
Before committing to a dedicated server for a business-critical inference API, request a fixed-scope cost estimate from at least two Dedicated Server Hosting in India providers and compare it against a scaled-out VPS Hosting in India setup running the same benchmark load. Comparing real numbers side by side, instead of assuming, is the only reliable way to settle VPS vs Dedicated for your specific traffic profile.
8. Infrastructure Readiness for Inference Deployment
Regardless of which side of the VPS vs Dedicated decision you land on, the underlying hosting and network infrastructure plays a major role in whether your inference API actually performs as expected in production.
- A dependable Web Hosting Company in India that understands both virtualised and bare-metal environments is well positioned to advise on which option fits your specific model.
- Businesses running hybrid inference pipelines need to confirm their infrastructure can support the technical requirements tied to their choice, whether that is GPU passthrough on a virtual server or full driver-level access on Dedicated Server Hosting in India.
- Network latency, NVMe storage performance, and uptime guarantees matter differently depending on the path chosen — a dedicated GPU server serving real-time inference is far more sensitive to network design than a lightweight VPS running batch jobs.
- Reliable Fully Managed VPS Hosting gives smaller AI teams the operational bandwidth to focus on model quality instead of firefighting basic infrastructure issues mid-deployment.
- Teams that outgrow Fully Managed VPS Hosting usually notice the signs early: rising p99 latency, GPU queueing, and support tickets about throttled CPU cycles.
- Cloudminister’s Dedicated Server Hosting in India offering is one option worth evaluating for teams that have already outgrown a VPS-based inference setup and need predictable GPU throughput.
- Organisations planning a multi-region inference rollout should confirm their hosting partner supports the data residency requirements relevant to their traffic, whether through Fully Managed VPS Hosting or Dedicated Servers in India.
- A Web Hosting Company in India with clear escalation paths and 24×7 support reduces operational risk during traffic spikes, regardless of which option is in play.
Any organisation deploying an inference API should run a fresh identity and access review as part of its go-live plan, regardless of whether the workload sits on a VPS or a dedicated server. Inference endpoints frequently expose more than intended through verbose error messages or overly permissive API keys, and cleaning this up before launch is far cheaper than discovering the gap after a security incident. A trustworthy Web Hosting Company in India should support this review as part of onboarding, not treat it as an extra billable service.
9. This Decision for Small and Mid-Sized AI Teams in India
Large AI labs had the budget to skip straight to dedicated GPU clusters, but small and mid-sized Indian AI teams are increasingly working through the VPS vs Dedicated decision as inference-focused hosting options expand to serve smaller teams.
- Early-stage teams typically cannot absorb a large upfront infrastructure commitment, so starting on VPS Hosting in India and migrating later matters even more for smaller organisations.
- Many Indian AI startups find that a VPS is the most practical starting point for their inference API, since it delivers quick deployment without demanding a dedicated infrastructure team.
- Lean teams without a dedicated DevOps engineer benefit from Fully Managed VPS Hosting, since the provider handles patching, monitoring, and uptime while the team focuses on the model itself.
- Fully Managed VPS Hosting also typically bundles basic monitoring dashboards, which small teams would otherwise have to configure themselves.
- Reviewing what a Fully Managed VPS Hosting plan actually includes, rather than assuming, avoids surprises when a support ticket goes unanswered during a traffic spike.
- Choosing the right hosting partner upfront avoids the common startup mistake of over-provisioning a dedicated server that then sits underused, quietly eroding runway.
- For a lean AI team, a Fully Managed VPS Hosting plan paired with a clear migration trigger (a specific request-volume threshold) often delivers the fastest path to sustainable inference hosting.
- Teams weighing Web Hosting Company in India options against building their own GPU infrastructure almost always come out ahead choosing a managed provider, given how quickly self-managed GPU costs grow with scale.
- Startups exploring Dedicated Server Hosting in India for the first time should ask specifically about minimum contract terms before committing, since flexibility matters at this stage.
- Partnering with a Web Hosting Company in India that understands both VPS Hosting in India and Dedicated Server Hosting in India, and the practical trade-offs between them, helps startups avoid the friction points that often derail early-stage AI products.
10. Common Mistakes That Undermine an Inference Deployment
Even with a solid framework, many inference deployments underdeliver, not because VPS vs Dedicated is the wrong question, but because of avoidable execution mistakes.
- Defaulting to a VPS for a large GPU-bound model just because it was the cheapest option at prototype stage.
- Defaulting to a dedicated server too early, before traffic actually justifies the fixed cost, and burning runway on idle capacity.
- Skipping a proper load test before launch, leading to latency surprises the moment real users hit the API.
- Underestimating GPU memory requirements, causing out-of-memory failures under concurrent load, whether the workload runs on Fully Managed VPS Hosting or on Dedicated Servers in India.
- Not monitoring p95 and p99 latency post-launch, which makes it difficult to know whether the current infrastructure choice is still the right one.
- Ignoring the underlying hosting provider’s network stability, which can undercut whatever performance gains the correct infrastructure choice was meant to deliver.
Businesses that pick a Web Hosting Company in India based on price alone, without checking GPU availability and support quality, often end up migrating twice: once to get the inference API live, and again to fix the problems that surfaced after launch.
Industry research into large-scale AI deployments consistently finds that the gap between smooth and troubled inference rollouts is rarely about the model itself. It is almost always an infrastructure planning gap. Teams that treat the VPS vs Dedicated decision as deliberate and workload-specific, backed by load testing and latency monitoring, consistently report smoother production performance than teams that pick one option by default and never revisit it.
11. Security, Compliance, and DPDPA 2023 Considerations for Inference APIs
Running an inference API means processing user input, sometimes including personal data, and returning model output over the network. For Indian businesses, this raises specific compliance questions under the DPDPA 2023 that apply regardless of the VPS vs Dedicated decision.
- Data fiduciaries remain responsible for how personal data is processed by an inference API even when the underlying compute is hosted on shared VPS infrastructure.
- Businesses should document whether their inference workload runs on VPS Hosting in India or a dedicated server as part of demonstrating reasonable technical safeguards under DPDPA 2023.
- Access logs and API key rotation policies become more important for inference endpoints, since a leaked key can expose both the model and any user data passed through it.
- Data residency commitments should be confirmed before deployment, particularly for any specific categories of data where your organisation has residency obligations, whether contractual, sectoral, or regulatory.
- Even businesses relying on affordable virtual server plans for smaller inference workloads should not skip this compliance step, since DPDPA 2023 applies regardless of hosting tier or budget.
- Teams choosing Dedicated Server Hosting in India specifically for data-isolation reasons should still document the reasoning, since “dedicated” alone is not automatically a compliance guarantee without proper configuration.
Checklist: Pre-Deployment Compliance Checklist for Inference APIs
- Map which categories of user data pass through the inference API
- Run a permissions and API-key audit across the hosting environment
- Confirm whether the VPS vs Dedicated decision affects your data residency obligations
- Review data isolation guarantees against your chosen hosting provider
- Rate-limit and log all inference requests for auditability
- Schedule a post-launch compliance review within 90 days of go-live
12. Customised Hosting Plans by AI Team Size
Not every AI team should approach VPS vs Dedicated the same way. A five-person startup shipping its first model has fundamentally different needs than a 200-person enterprise AI division.
- Small teams often see the fastest path to production with a straightforward virtual server plan, since speed and simplicity matter more than deep optimisation at this stage.
- Mid-sized AI teams tend to benefit from a hybrid approach, running preprocessing on a VPS while routing the actual model inference to Dedicated Servers in India once volume justifies it.
- Larger enterprises typically need a phased rollout that applies both VPS and Dedicated Servers in India across different models and services in their stack.
- Every inference deployment plan should include a feedback loop back to engineering leadership so an underperforming infrastructure choice can be revisited before the next model ships.
- Smaller teams following a VPS-first approach should periodically compare their current VPS Hosting in India spend against newer Fully Managed VPS Hosting plans, since pricing in this segment shifts frequently.
- Growing AI teams evaluating Dedicated Servers in India for the first time should size their commitment against realistic six-month traffic projections, not just current volume.
- Enterprises already running Dedicated Servers in India for one model often find it cost-effective to consolidate additional models onto the same hardware footprint rather than provisioning separately, mirroring the consolidation many teams already do on Fully Managed VPS Hosting.
- Teams that started on Dedicated Servers in India for a single flagship model frequently expand that same contract to cover secondary models once volume justifies it.
Assign a small internal review group with representation from engineering, finance, and whoever owns the product roadmap before finalising the VPS vs Dedicated decision for a new inference API. Cross-functional input consistently produces better infrastructure choices than engineering making the call in isolation, and looping in your Web Hosting Company in India early often surfaces trade-offs the group would otherwise miss.
13. Measuring Success Beyond Launch
Initial momentum around an inference API deployment tends to fade if performance is not actively measured after go-live. Long-term success requires treating the VPS vs Dedicated decision as an ongoing operational choice rather than a one-time setup step.
- Set a recurring monthly review comparing actual latency, throughput, and cost-per-inference against the assumptions made when the original choice was first decided.
- Revisit the decision whenever request volume grows meaningfully, since VPS Hosting in India that worked at launch may not hold up six months later.
- Compare renewal-time infrastructure costs against the performance actually achieved, not against the original business case alone.
- Reassess whether the original VPS vs Dedicated choice still holds as model size, user base, and traffic patterns shift over time.
- Maintain close coordination between engineering, finance, and product so new models entering the roadmap are evaluated for hosting needs from day one.
Businesses should also revisit whether their current Web Hosting Company in India relationship, or the VPS Hosting in India plan chosen early on, still matches their scale a year or two after their first inference API went live.
As inference traffic scales, periodically re-run the permissions and API-key audit described earlier in this guide. Team structures change, models get replaced, and ownership of endpoints shifts, outdated access permissions remain one of the most common sources of unintended data exposure following any AI deployment, regardless of whether it runs on VPS Hosting in India or Dedicated Servers in India.
14. Choosing the Right Infrastructure Partner
Strategy gets most of the attention during planning, but the hosting partner behind either side of the VPS vs Dedicated decision plays an equally important role in whether the deployment actually succeeds.
- A dependable Web Hosting Company in India that already understands inference workloads is well positioned to advise on whether VPS or dedicated fits your specific model and traffic pattern.
- Businesses that choose reliable Dedicated Server Hosting in India benefit from having a single point of accountability for GPU uptime, latency, and security during a traffic-sensitive launch window.
- Comparing Dedicated Server Hosting in India providers before finalising a GPU-heavy deployment is worth the extra week it takes, given how much the wrong infrastructure choice can cost later in downtime and migration effort.
- Engineering leaders who have not yet evaluated their hosting partner relationship should treat a new inference API launch as a natural trigger point to do so.
- Providers offering genuinely Fully Managed VPS Hosting free up internal engineering time that would otherwise go toward patching and uptime monitoring instead of model improvements.
- A provider that also offers Dedicated Servers in India under the same account makes the eventual migration far less disruptive than switching vendors mid-scale.
- A hosting partner that can speak fluently about both VPS Hosting in India and Dedicated Servers in India gives AI teams a single, coherent infrastructure roadmap instead of two disconnected vendor relationships.
The most effective infrastructure partners in 2026 no longer treat VPS and dedicated hosting as separate conversations. A Web Hosting Company in India that can walk a team through both VPS Hosting in India and Dedicated Server Hosting in India, and explain exactly where the VPS vs Dedicated line sits for a specific inference workload, gives AI teams a genuinely useful technology roadmap instead of a generic pricing sheet.
15. Quick Comparison: Matching Hosting Options to Your Inference Path
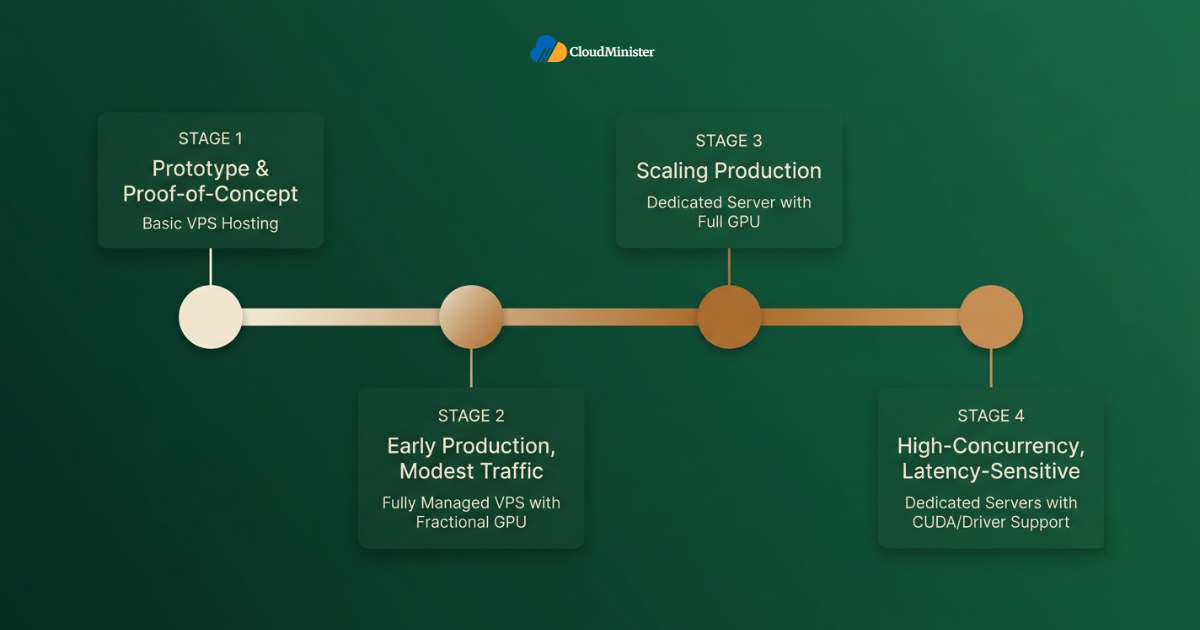
Different stages of an AI product call for different infrastructure. Here is a simple way to think through this decision at each stage.
- Prototype and proof-of-concept: basic VPS Hosting in India is usually sufficient, since these early tests do not demand GPU-level throughput.
- Early production with modest traffic: Fully Managed VPS Hosting with a fractional GPU tends to be the sweet spot for cost versus performance, before Dedicated Servers in India become necessary.
- Scaling production with real user traffic: this is typically where the VPS vs Dedicated decision tips toward a dedicated server with a full GPU allocation.
- High-concurrency, latency-sensitive inference: look for Dedicated Servers in India that explicitly support the CUDA and driver versions your model stack needs.
- Teams managing several models at once: a single Web Hosting Company in India partner handling both VPS and dedicated workloads simplifies vendor management considerably.
- Budget-conscious startups: comparing at least one VPS Hosting in India quote against a Dedicated Server Hosting in India quote before signing is a simple step that consistently protects runway, and asking specifically about Fully Managed VPS Hosting tiers can reveal hidden support gaps.
- Enterprises running multiple parallel inference services: a single provider offering both VPS vs Dedicated options under one account reduces operational overhead considerably.
Teams that have not yet compared their current VPS Hosting in India setup against Dedicated Servers in India, or checked whether their Web Hosting Company in India partner offers GPU-specific plans, should do so before their next model ships. Any business still weighing VPS vs Dedicated for its next inference API should treat the decision as part of the broader product launch plan, not a separate infrastructure afterthought.
Conclusion
AI inference in 2026 has clearly moved past the “should we deploy a model as an API” debate. With enterprise inference infrastructure spending now measured in the hundreds of billions of dollars and structured evaluation frameworks becoming standard practice, VPS vs Dedicated has established itself as the practical starting point for any serious inference hosting conversation. The teams seeing the strongest results share a common pattern: they evaluate VPS vs Dedicated honestly against their actual model size and traffic, document the reasoning, plan for DPDPA 2023 compliance from day one, and pair the decision with stable underlying infrastructure, not a single default choice applied to every model they ship.
For Indian AI teams in particular, pairing a well-planned decision with compliance discipline and a dependable Web Hosting Company in India for the surrounding infrastructure gives the best chance of turning an inference API into a reliable production system rather than a recurring source of downtime. Before closing out the planning phase, it is worth a final sanity check: confirm whether your chosen VPS Hosting in India provider, or your Dedicated Server Hosting in India relationship if you have already scaled that far, actually matches the specific inference workload you are running, not just the general category of “AI hosting.”
Not Sure Which Option Fits Your Workload?
Talk to our infrastructure team for a workload-specific recommendation on VPS vs Dedicated, backed by real benchmarking and DPDPA-aware planning.
Key Takeaways
- VPS vs Dedicated remains the standard way to evaluate inference hosting decisions in 2026, and the right answer depends entirely on model size and traffic, not company preference.
- No single option is universally correct; most growing AI products use a mix, starting on VPS Hosting in India and migrating specific workloads to Dedicated Servers in India as they scale.
- Global AI inference spending is projected to reach well over 100 billion dollars in 2026, reflecting how much production infrastructure now depends on getting this decision right.
- Choosing the correct option for each model avoids the common and costly mistake of applying one hosting strategy across an entire AI product portfolio.
- A clean permissions audit and DPDPA 2023 compliance review are essential steps before any inference API launch in an Indian business context.
- Underlying infrastructure quality, from Fully Managed VPS Hosting to well-managed Dedicated Servers in India, directly affects how well an inference API performs after go-live, and both deserve equal planning attention.
- Workload-by-workload planning consistently outperforms blanket infrastructure decisions, and teams evaluating VPS vs Dedicated should revisit the choice as traffic and model size evolve.
Frequently Asked Questions
What is the real difference in VPS vs Dedicated for AI inference?
The difference for inference comes down to resource isolation: a VPS shares a physical host’s CPU, RAM, and often GPU with other tenants, while a dedicated server gives your inference workload exclusive access to the entire machine.
Is a VPS ever good enough for production AI inference?
Yes. VPS Hosting in India works well for small models, low-traffic APIs, and internal tools. The VPS vs Dedicated decision typically shifts toward dedicated hardware once traffic, model size, or latency requirements grow past what shared resources can reliably support.
Which side of VPS vs Dedicated is cheaper?
It depends on scale. A VPS is usually cheaper at low request volume, while a dedicated server often becomes more cost-efficient per inference once concurrency and traffic cross a meaningful threshold.
How long does migrating from VPS to a dedicated server usually take?
Timelines vary based on model complexity and traffic volume, but most migrations for an active inference API take anywhere from a few days to a few weeks, including load testing before full cutover.
What should Indian AI teams check before choosing VPS vs Dedicated?
Indian AI teams should run a permissions and API-key audit, confirm DPDPA 2023 compliance documentation, verify their hosting provider supports the GPU and driver requirements of their chosen option, and ensure their infrastructure, ideally supported by an experienced Web Hosting Company in India, can reliably handle their expected inference volume.

Shivlendra Singh Jadoun is a Cloud & DevOps Engineer at CloudMinister Technologies, specializing in AWS, Azure, and GCP infrastructure. He began his career in Linux system administration, managing shared, VPS, and dedicated servers before moving into cloud and automation. He is AWS Certified and works extensively with Docker, Kubernetes, Terraform, Ansible, and Jenkins to build CI/CD pipelines and scalable, secure cloud environments. With hands-on experience across hosting, server security, and DevOps automation, he brings real-world engineering insight to every article he writes.