Customer support teams in 2026 are under constant pressure to respond faster while keeping headcount flat. An n8n AI agent solves this by combining n8n’s visual workflow builder with large language models, letting a business automate ticket triage, FAQ answers, and escalation logic without writing a full backend. This guide is a complete, technically accurate walkthrough for building an n8n AI agent for customer support: architecture, node setup, memory, tool calling, hosting, security, and scaling. Enterprise adoption of autonomous agents is expected to cross roughly 37 percent in 2026, and customer service is one of the leading use cases for this shift toward agent-based automation.
This kind of workflow is not a chatbot bolted onto a website. It is a system that can read an incoming support ticket, decide what the customer actually needs, pull data from a CRM or knowledge base, and either resolve the query or hand it to a human with full context attached. Building one properly means understanding both the underlying reasoning node and the infrastructure it runs on.
This blog gives support teams, founders, and automation engineers a practical, step-by-step path to building an n8n AI agent, covering what it actually does inside n8n, which nodes and models to use, how to structure memory and tools, how to deploy it reliably, and how to keep customer data secure while scaling across more support channels.
1. What Is an n8n AI Agent – And Why Customer Support Teams Need One in 2026
An n8n AI agent is a workflow built inside n8n that uses a large language model as its reasoning engine, combined with tools, memory, and conditional logic, to handle tasks autonomously instead of following a single fixed script. For customer support, this setup answers practical operational questions:
- Can this ticket be resolved instantly from existing documentation?
- Does this customer need order status, refund eligibility, or account access details pulled from a live system?
- Should this conversation be escalated to a human agent, and with what context?
- Which support channel – email, live chat, or WhatsApp – is generating the highest ticket volume right now?
- Is the response accurate enough to send automatically, or does it need a human review step first?
The core building blocks of an n8n AI agent, in order of how a support workflow typically assembles them:
| Component | Role in the Workflow | Support Use Case Example |
| Trigger Node | Starts the workflow | New ticket arrives via email or webhook |
| Reasoning Node | Decision-making core | Classify intent and choose next action |
| Tool Nodes | Give the workflow capabilities | Look up order status in Shopify or CRM |
| Memory Node | Retains conversation context | Recall earlier messages in the same thread |
| Output / Action Node | Executes the final step | Send reply, create ticket, escalate to human |
Most support teams start with a simple version that only classifies and replies to FAQs, then expand toward an n8n AI agent capable of taking real actions like issuing refunds or updating CRM records. The infrastructure decisions made early, particularly the choice of a reliable Web Hosting Company in India or self-hosted server for running the workflow engine, directly determine whether replies come back in under two seconds or time out under real traffic. Businesses comparing n8n VPS hosting India options at this stage should look closely at CPU allocation and storage type, since both affect how consistently the workflow performs once real customers start using it.
2. The Customer Support Automation Market Context in 2026
The commercial case for building an n8n AI agent for support is strong. Contact centers deploying autonomous agents are expected to reduce cost-per-contact by twenty to forty percent by 2026 as routine Tier-1 resolution becomes fully automated, according to industry research on agentic AI adoption (Second Talent, 2026). Separately, customer service ranks among the top business use cases for AI agents globally, with research showing customer service adoption sits close to forty-six percent among organizations already running agents in production (Panto AI, 2026).
| Metric | Figure | Relevance to This Kind of Deployment |
| Cost-per-contact reduction | 20–40% by 2026 | Direct ROI case for Tier-1 automation |
| n8n active global users | 230,000+ | Mature, proven platform for building agents |
| n8n official integrations | 1,300+ nodes | Wide tool access for a support-focused agent |
| Enterprise autonomous agent adoption | ~37% in 2026 | Support automation is now mainstream, not experimental |
| Organizations citing customer service as top use case | 45.8% | Support is one of the highest-value agent deployments |
An n8n AI agent built for support sits directly on this growth curve. Businesses that treat support automation as core infrastructure, rather than a side experiment, are the ones capturing the cost and speed advantage described above. This is also why the hosting layer beneath the workflow matters so much, a slow or unstable server undermines every efficiency gain the automation is meant to deliver. A Web Hosting Company in India that understands both webhook reliability and database performance is a better long-term partner than a generic shared hosting reseller.
RELATED READING: What Is n8n? A Beginner’s Guide to the No-Code Workflow Automation Tool
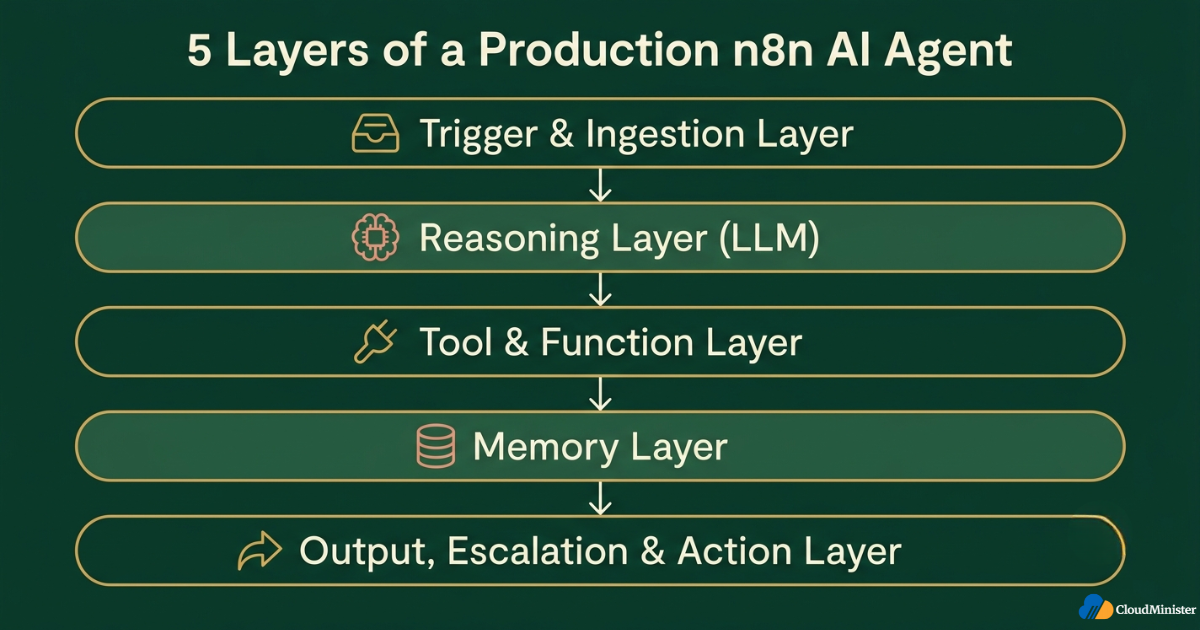
3. Core Architecture of an n8n AI Agent for Support – Five Layers
A production-grade n8n AI agent is a layered system, not a single node dropped into a canvas. Skipping any layer, especially memory or tool access control, creates a workflow that hallucinates answers or takes unsafe actions.
3.1 Trigger and Ingestion Layer
Every deployment begins with a trigger that captures the incoming support request:
- Email trigger nodes (IMAP or Gmail) for ticket-based support
- Webhook nodes for live chat widgets, WhatsApp Business API, or a helpdesk platform
- Form trigger nodes for structured support requests submitted via a website
- Scheduled polling for platforms without native webhook support
Before wiring the reasoning node, map every channel your support team currently uses. An n8n AI agent that only watches email while your customers are messaging on WhatsApp will miss the majority of real ticket volume, producing an incomplete automation layer regardless of how well the workflow itself is configured.
3.2 The Reasoning Layer
This is the core of the workflow. The n8n AI agent node wraps a large language model and gives it the ability to reason, plan, and decide which tool to call next:
- Model connection: OpenAI, Anthropic Claude, or a self-hosted open-weight model connected via API
- System prompt: Defines tone, scope, escalation rules, and what the workflow is not allowed to do
- Agent type: Tools Agent (most common for support), Conversational Agent, or a custom ReAct-style setup
- Output parser: Structures the response so downstream nodes can act on it reliably
For teams running larger models or fine-tuned open-weight LLMs locally instead of calling a third-party API, inference speed depends entirely on the compute behind it. A Dedicated NVIDIA GPU Server provides the parallel processing power needed to run inference for a self-hosted n8n AI agent without the latency spikes common on shared or CPU-only infrastructure. Comparing providers on best GPU cloud hosting benchmarks before committing is worth the extra hour of research, since inference speed directly shapes how natural the support conversation feels to the customer on the other end.
3.3 Tool and Function Layer
An n8n AI agent is only as useful as the tools it can call. Tools give the workflow the ability to act, not just talk:
- HTTP Request tool: Calls internal or third-party APIs — CRM lookups, order status, shipment tracking
- Vector Store tool: Retrieves relevant documentation chunks for grounded, accurate answers
- Code tool: Runs custom JavaScript or Python logic for calculations the model should not attempt itself
- Sub-workflow tool: Delegates a complex task to another n8n workflow, keeping the main agent lean
When building your first n8n AI agent for support, give it only two or three tools to start, order lookup and a knowledge base search are usually enough. A workflow overloaded with fifteen tools on day one tends to pick the wrong tool more often; add capability gradually as accuracy is proven.
3.4 Memory Layer
Support conversations rarely resolve in a single message, so an n8n AI agent needs memory to stay coherent across a thread:
- Window Buffer Memory: Retains the last several messages, simplest option for most support workflows
- Vector Store-backed Memory: Stores long-term customer history for repeat interactions
- Custom database memory: PostgreSQL or Redis-backed memory for full control over retention and privacy
Memory state for this kind of workflow should be stored on infrastructure with predictable, low-latency disk access, since every reasoning step reads and writes context. Self-Hosted N8N VPS Hosting with NVMe storage keeps this read-write cycle fast even as conversation history and vector embeddings grow. Teams evaluating n8n VPS hosting India providers for this exact reason should confirm NVMe is standard on the plan, not an optional add-on.
3.5 Output, Escalation, and Action Layer
The final layer converts the reasoning node’s decision into a real-world outcome:
- Auto-reply nodes: Send the response directly through email, chat, or WhatsApp
- Escalation nodes: Route the conversation to a human agent in Zendesk, Freshdesk, or Intercom with full context
- Logging nodes: Record every decision made for audit and quality review
- Feedback loop nodes: Capture customer satisfaction signals to retrain prompts over time
4. Step-by-Step: Building Your n8n AI Agent for Customer Support
Phase 1: Define the Support Use Case (Days 1–2)
An n8n AI agent built without a clear scope tends to either underperform or overreach. Start narrow:
- List the five most repetitive ticket types your support team handles today
- Identify which of these can be safely automated end-to-end versus which need human review
- Define what a successful resolution looks like for each ticket type
- Confirm the data the workflow will need — order data, account data, policy documents, is actually accessible via API
The best first use case for an n8n AI agent is order status and shipment tracking. It is high volume, low risk, and the data usually already lives in a clean API. Prove the workflow works here before letting it touch refunds or account changes.
Phase 2: Set Up n8n and Connect Your Model (Days 2–4)
- Deploy n8n on a server you control if data privacy or customization is a priority, self-hosting on Self-Hosted N8N VPS Hosting is the standard approach for a production n8n AI agent handling customer data
- Connect your chosen LLM provider credentials inside n8n’s credential manager
- Add the reasoning node to a new workflow and select the Tools Agent type
- Write a clear, constrained system prompt defining exactly what the workflow can and cannot do
RELATED READING: Best N8N Hosting Providers Compared
Phase 3: Build the Trigger and Connect Support Channels (Days 3–6)
- Configure the email or webhook trigger matching your primary support channel
- Test the trigger in isolation before connecting it to the reasoning node
- Normalize incoming data — sender, subject, message body — into a consistent format the workflow can reason over
- Add a filter node to route spam or clearly irrelevant messages away from the agent entirely
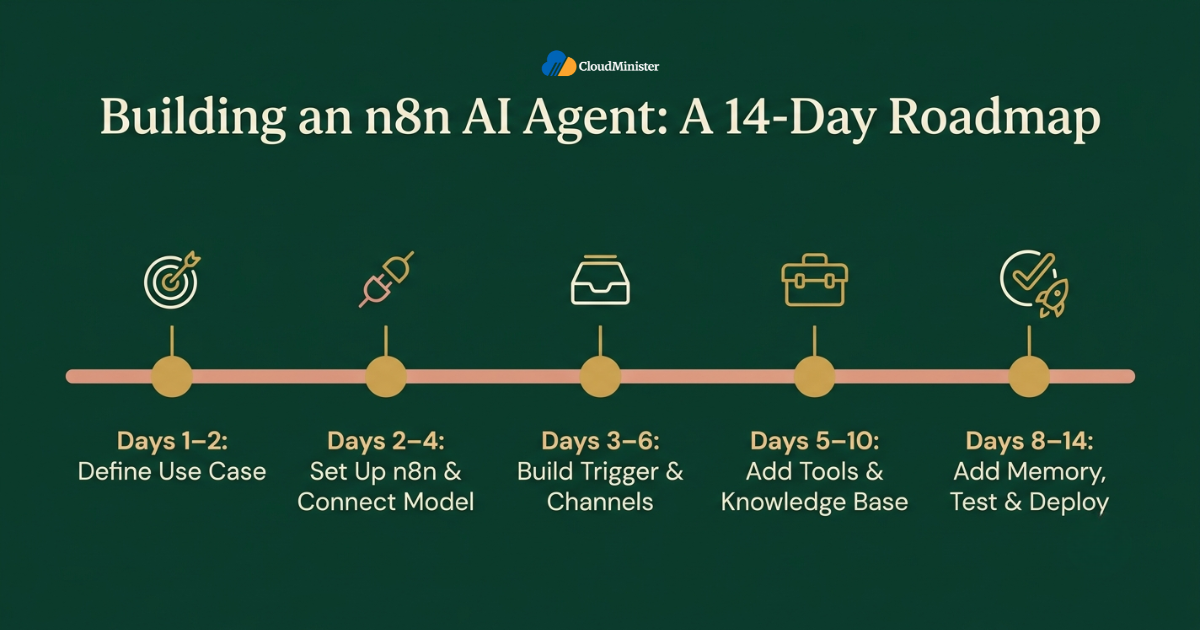
Phase 4: Add Tools and Knowledge Base Access (Days 5–10)
- Connect an HTTP Request tool to your CRM or order management system
- Build a Vector Store using your help center articles, product docs, and policy pages so the n8n AI agent answers from real documentation, not guesses
- Test each tool independently before letting the workflow call it autonomously
- Validate that tool responses are structured cleanly enough for the agent to parse without errors
An n8n AI agent handling customer support data is processing personal information under India’s DPDPA 2023 obligations. Apply strong access controls and encryption to any database the workflow queries, log every tool call it makes, and never let it write directly to production customer records without a review or approval step. While DPDPA 2023 does not strictly mandate India-only data storage, teams should still review data transfer and processing obligations carefully based on their specific setup.
Phase 5: Add Memory, Test, and Deploy (Days 8–14)
- Attach a memory node so the workflow retains context across a multi-message conversation
- Run structured test conversations covering common tickets, edge cases, and deliberately confusing inputs
- Add a human-in-the-loop approval step for any action involving refunds, cancellations, or account changes
- Deploy the n8n AI agent and monitor the first two weeks of live traffic closely before expanding scope
RELATED READING: Best Server Setup and Security Practices for Hosting n8n Workflows
5. Choosing the Right Model and Infrastructure for Your n8n AI Agent
5.1 Model Selection
| Approach | Best For | Cost Profile | Notes |
| Hosted API (OpenAI, Anthropic) | Fastest setup, no infra | Pay-per-token | Simplest way to launch |
| Self-hosted open-weight model | Data privacy, high volume | Upfront GPU cost | Needs dedicated compute for real-time replies |
| Hybrid (API + local fallback) | Cost control at scale | Mixed | Common pattern once volume grows |
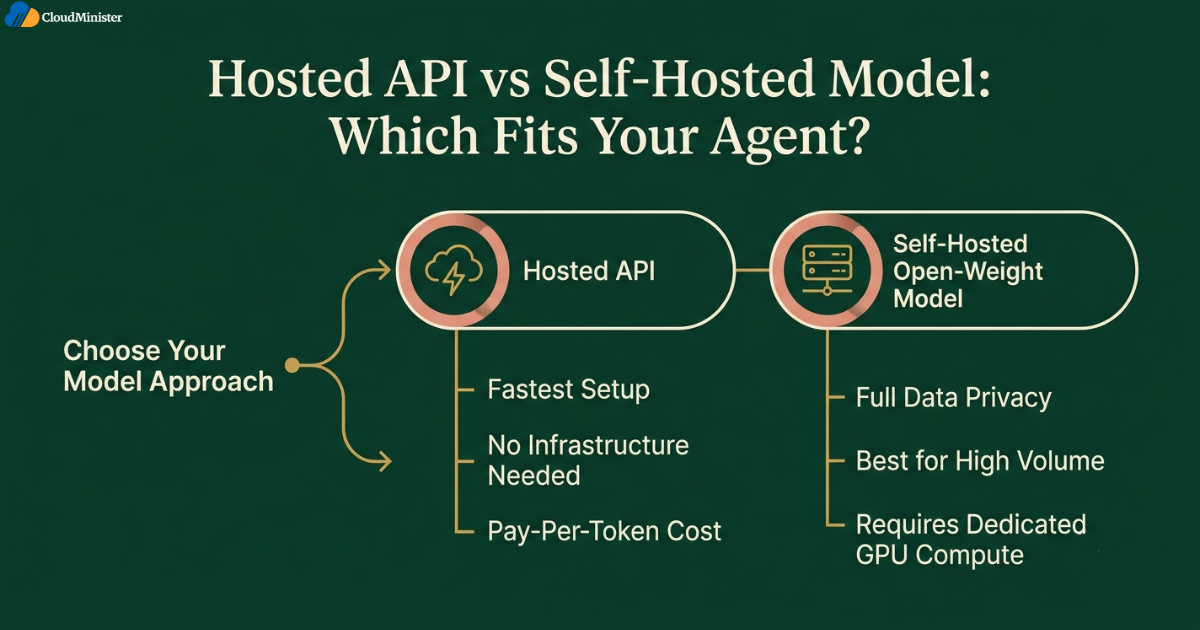
Calling a hosted API is the fastest way to get an n8n AI agent started and works well for most small and mid-sized support teams, and it also avoids the upfront cost of a Dedicated NVIDIA GPU Server. As ticket volume grows into the tens of thousands per month, or when customer data cannot leave a private environment, a self-hosted model becomes the more sustainable option — and that is where compute becomes the deciding factor for reliability.
5.2 Why GPU Compute Matters for Self-Hosted Agents
- Inference latency: Every reasoning step in the tool-calling loop depends on how fast the model responds — slow inference compounds across multi-step conversations
- Concurrent conversations: Support volume spikes during business hours; a self-hosted setup needs enough parallel throughput to avoid a queue building up
- Embedding generation: Vector Store tools require embedding models running continuously as documentation updates, adding sustained compute load
- Model size: Larger open-weight models produce noticeably better reasoning for complex support queries, but require proportionally more VRAM, which is exactly where best GPU cloud hosting comparisons become useful, so shortlist at least two best GPU cloud hosting providers before committing
A Dedicated NVIDIA GPU Server removes the shared-tenancy bottlenecks that cause inconsistent response times when a self-hosted n8n AI agent is under real customer load. Teams evaluating options for best GPU cloud hosting for this kind of workload should prioritize dedicated VRAM allocation and consistent network throughput over raw sticker price, since a support workflow that responds inconsistently is worse for customer trust than one that is simply on a hosted API. A Dedicated NVIDIA GPU Server also scales more predictably than a shared GPU instance once concurrent conversation volume climbs past a few dozen sessions at once. When shortlisting best GPU cloud hosting providers, request a benchmark run with your actual model rather than relying on published specification sheets, since real-world best GPU cloud hosting performance can vary meaningfully between providers advertising identical hardware.
RELATED READING GPU Cloud Providers in India Compared
5.3 Hosting n8n Itself
n8n, the workflow engine running your agent, also needs a stable home separate from the model inference layer:
- Shared hosting is not suitable for a production n8n AI agent — webhook reliability and persistent connections both suffer under shared CPU and connection limits
- Self-Hosted N8N VPS Hosting gives the workflow engine dedicated resources, so trigger nodes and the reasoning node itself are not competing with unrelated tenants for CPU cycles
- A Web Hosting Company in India with India-based data centers helps meet data residency expectations when the workflow processes customer PII
- NVMe-backed storage keeps workflow execution logs and memory lookups fast as conversation volume grows
- Businesses searching specifically for n8n VPS hosting India plans should confirm dedicated vCPU allocation is included, not just burstable shared cores
| Hosting Type | Suitable for This Workload? | Notes |
| Shared Hosting | No | Webhook and connection limits break reliability |
| Self-Hosted N8N VPS Hosting | Yes — most teams | Dedicated resources, predictable performance |
| Dedicated Server | Yes — high volume | Needed above roughly 15 concurrent support sessions |
| Managed Cloud | Yes | Good when already standardized on AWS or GCP |
A Web Hosting Company in India offering Self-Hosted N8N VPS Hosting as a dedicated product, rather than a generic VPS repurposed for the job, tends to have better default configurations for webhook uptime and persistent database connections.
Ready to Self-Host Your n8n AI Agent?
Get dedicated NVMe-powered n8n VPS hosting with root access, 99.99% uptime, and 24/7 expert support, built for reliable, production-grade workflow automation.
6. Industry Use Cases for an n8n AI Agent in Customer Support
6.1 E-Commerce
- Order status and shipment tracking answered instantly without human involvement
- Return and refund eligibility checks against policy documents before routing to a human for final approval
- Abandoned cart follow-up messages triggered and personalized based on browsing history
E-commerce brands running high ticket volumes often choose n8n VPS hosting India plans specifically for this workload, since order and shipment lookups happen constantly throughout the day and need consistent response times.
6.2 SaaS and Software Companies
- Tier-1 technical support answering setup and configuration questions from product documentation
- Bug report triage where the workflow classifies severity and routes to the correct engineering queue
- Renewal and billing queries answered directly from subscription data pulled via API
SaaS companies self-hosting an open-weight model for cost control at scale typically pair it with a Dedicated NVIDIA GPU Server, since API costs on high ticket volumes can exceed the price of dedicated compute within a few months.
6.3 Healthcare and Diagnostics Support Lines
- Appointment rescheduling handled by an n8n AI agent, with all patient data processed on India-based infrastructure
- General service queries answered instantly, with any clinical question automatically escalated to a human
Healthcare support workflows built this way must treat all patient data under DPDPA 2023 obligations. Run the database and workflow engine on infrastructure offering ISO 27001 certification and encryption at rest, and ensure clinical questions are never auto-resolved without human sign-off. Data residency requirements should be assessed based on your specific compliance posture, since DPDPA 2023 does not strictly mandate India-only storage. A Web Hosting Company in India with healthcare-grade compliance credentials is the right partner for this kind of workload, rather than a generic international provider.
6.4 Logistics and Delivery
- Delivery status and ETA queries resolved instantly by pulling live tracking data
- Failed delivery follow-up automatically scheduling redelivery or refund workflows
Logistics operators running fleets across multiple cities often standardize on n8n VPS hosting India for the workflow engine and a Web Hosting Company in India for their broader website and application stack, keeping both under a single reliable vendor relationship.
RELATED READING Best N8N Hosting Providers Compared
7. Security and Compliance for an n8n AI Agent Handling Customer Data
7.1 DPDPA 2023 Obligations
An n8n AI agent processing personal data of Indian customers falls directly under DPDPA 2023:
- Data minimization: Only pass the fields actually needed into the model context, do not forward entire customer records for a simple order lookup
- Purpose limitation: Data collected for support resolution should not be repurposed for marketing without fresh consent
- Data residency: While DPDPA 2023 does not strictly mandate India-only data storage, businesses should assess cross-border data transfer implications and choose infrastructure that aligns with their specific compliance and risk posture.
- Audit logging: Every tool call and model response inside the workflow should be logged for review
7.2 Access Control
- Role-based access: Separate credentials for workflow administrators, support reviewers, and the service account the agent itself uses
- Least-privilege API keys: The CRM and helpdesk credentials should only allow the specific actions needed, nothing broader
- Encryption: All data at rest and in transit around the workflow should be encrypted, AES-256 at minimum
A reputable Web Hosting Company in India will typically offer managed firewall rules and access logging as part of Self-Hosted N8N VPS Hosting plans, which removes a meaningful chunk of this configuration burden from the support team.
SECURITY NOTE
The most common failure in production n8n AI agent deployments is an overly broad API key or database role handed to the service account. Audit every credential the workflow uses on a quarterly basis, and prefer infrastructure providers offering managed security monitoring as standard, whether that is on Self-Hosted N8N VPS Hosting or a Dedicated NVIDIA GPU Server running the inference layer.
8. Readiness Checklist Before Launching Your n8n AI Agent
- Use case defined: A single, high-volume, low-risk support scenario chosen as the first target
- Data sources mapped: CRM, helpdesk, and knowledge base access confirmed and API-tested
- Model selected: Hosted API or self-hosted model decision made based on volume and privacy needs
- Infrastructure provisioned: Self-Hosted N8N VPS Hosting or dedicated compute ready for production load
- Prompt and scope defined: System prompt clearly states what the workflow can and cannot do
- Human-in-the-loop configured: Sensitive actions require approval before execution
- Security reviewed: DPDPA 2023 scope assessed, access controls and audit logging in place
- Testing completed: Common tickets, edge cases, and failure modes all tested before go-live
- Monitoring in place: Logging and alerting configured to catch errors quickly after launch
PRO TIP
Run this checklist before pointing any real customer traffic at your n8n AI agent. The most expensive mistake support teams make is deploying to production before the underlying data access, memory, and hosting layers are actually ready to support it reliably.
9. Costs of Running an n8n AI Agent for Support
| Tier | Stack | Monthly Cost Range (INR) | Suitable For |
| Starter | n8n self-hosted + hosted LLM API | ₹3,000–₹8,000 | Small teams, low ticket volume |
| Growth | n8n on Self-Hosted N8N VPS Hosting + hosted API | ₹8,000–₹20,000 | Mid-volume support, multiple channels |
| Scale | n8n VPS hosting India tier + fine-tuned model | ₹25,000–₹60,000 | High volume, custom model behavior |
| Enterprise | n8n on dedicated compute + self-hosted GPU inference | ₹70,000–₹1,50,000+ | Full data privacy, very high volume |
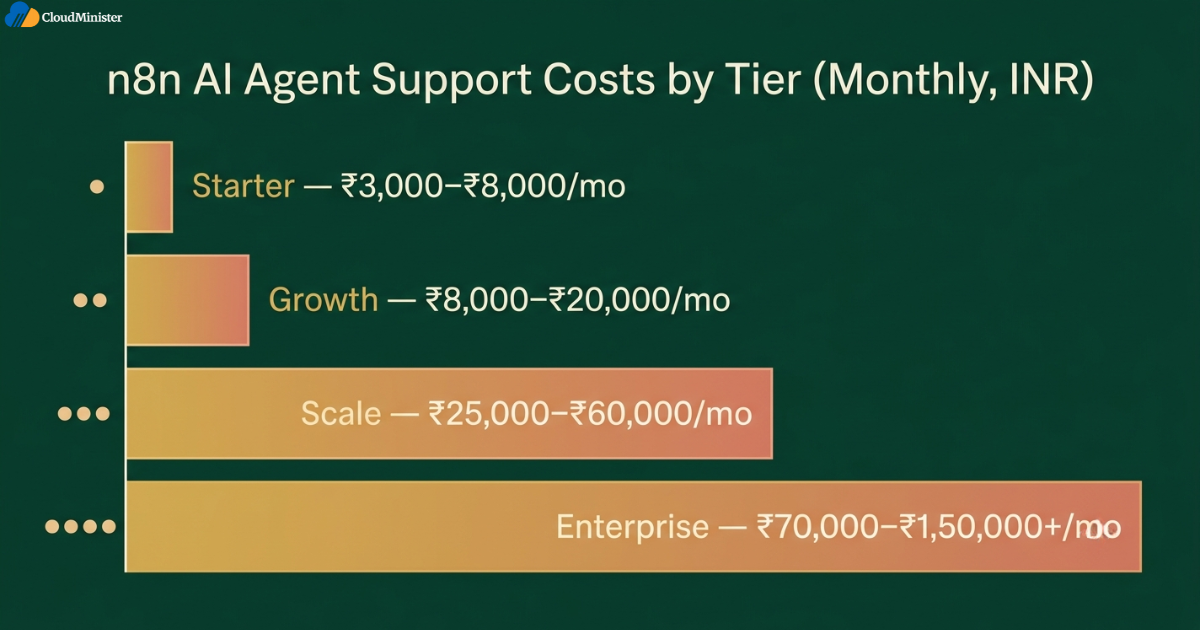
The growth tier, n8n running on a properly resourced VPS with a hosted model API, is the practical starting point for most support teams building their first n8n AI agent, with a clear upgrade path toward self-hosted inference as volume and privacy requirements increase. Businesses comparing n8n VPS hosting India pricing at the growth tier should factor in RAM headroom for the vector store, not just the base disk size advertised. At the enterprise tier, the jump in cost is almost entirely attributable to running a Dedicated NVIDIA GPU Server rather than calling a third-party API, and it is worth benchmarking best GPU cloud hosting options side by side before locking into a long-term contract, since GPU pricing varies significantly between providers offering similar specifications.
10. Scaling Your n8n AI Agent Over Time
- Expand tool access gradually: Add refund processing or account changes only after the base workflow proves reliable on lower-risk tasks
- Separate workflows by channel: Running one enormous n8n AI agent for email, chat, and WhatsApp simultaneously makes debugging harder than running focused, connected workflows
- Monitor token costs: A workflow calling a hosted API scales cost with conversation volume — track this closely as adoption grows
- Upgrade infrastructure proactively: Move from shared or entry VPS tiers to a Dedicated NVIDIA GPU Server or larger VPS before response times start degrading, not after
- Retrain and refine prompts: Use logged conversations to continuously improve the system prompt and tool selection accuracy
- Reassess hosting annually: A Web Hosting Company in India that fit a starter deployment may not have the right tier once concurrent sessions climb into the dozens, so revisit n8n VPS hosting India options as volume grows, and check whether a Dedicated NVIDIA GPU Server is now more economical than continued API spend
The most common scaling failure for an n8n AI agent is infrastructure that was sized for the pilot, not for production. A workflow that runs perfectly for fifty test tickets a day can fall over at five thousand real tickets a day without the right compute and storage behind it. Businesses that benchmark best GPU cloud hosting providers early, before they actually need the extra throughput, tend to avoid painful mid-migration downtime later. The same applies to n8n VPS hosting India plans — testing headroom before it is needed is far cheaper than an emergency upgrade during a traffic spike, and a Web Hosting Company in India with a fast upgrade path can make that transition close to seamless. Comparing best GPU cloud hosting shortlists against your actual n8n VPS hosting India spend gives a clearer picture of total infrastructure cost than looking at either number in isolation.
KEY TAKEAWAYS
- An n8n AI agent combines n8n’s visual workflow builder with an LLM’s reasoning ability to automate real customer support tasks, not just answer FAQs.
- Contact centers using autonomous agents can cut cost-per-contact by 20 to 40 percent by 2026, making a strong ROI case for building one.
- A production n8n AI agent has five layers: trigger, reasoning, tools, memory, and output/escalation.
- Self-Hosted N8N VPS Hosting is the practical infrastructure tier for most teams, with a Dedicated NVIDIA GPU Server needed for self-hosted model inference at scale.
- DPDPA 2023 requires India-based data residency, role-based access, and audit logging for any workflow touching customer PII.
- Start narrow with one use case, prove reliability, and expand scope gradually rather than automating everything on day one.
Need Help Planning Your n8n AI Agent Infrastructure?
Talk to our team about choosing the right hosting setup, from n8n VPS to GPU inference, for your customer support automation.
Conclusion
Building an n8n AI agent for customer support in 2026 is no longer an advanced engineering project reserved for large enterprises. With n8n’s mature node ecosystem, accessible LLM APIs, and the option to self-host both the workflow engine and the model itself, a support team of any size can move from manual ticket handling to a reliable, monitored automation within a matter of weeks. The path outlined here, define the use case, build the trigger and reasoning layer, add tools and memory carefully, secure the data, and scale gradually, applies regardless of industry or team size. Businesses that pair a well-scoped n8n AI agent with the right hosting foundation, whether that is Self-Hosted N8N VPS Hosting for the workflow engine or a Dedicated NVIDIA GPU Server for self-hosted inference, are the ones seeing the cost and speed advantage described throughout this guide. CloudMinister, a trusted Web Hosting Company in India, provides n8n VPS hosting India plans, Dedicated NVIDIA GPU Server infrastructure, and managed operations built specifically for teams running production n8n AI agent workloads.
11. Choosing Between Providers for the Two Infrastructure Layers
Two separate infrastructure decisions sit underneath this entire setup, and it helps to treat them as distinct evaluations rather than one bundled choice.
The workflow engine layer: This is where n8n itself lives, along with its database and execution logs. Self-Hosted N8N VPS Hosting is purpose-built for exactly this layer, and a Web Hosting Company in India offering it as a dedicated plan, rather than a generic VPS repurposed for the job, typically ships with better default firewall rules, automated backups, and webhook-friendly networking out of the box.
The model inference layer: This only matters if a self-hosted open-weight model is in the picture. Here, the relevant comparison shifts to best GPU cloud hosting providers rather than standard VPS plans, since GPU workloads have entirely different pricing, provisioning, and support requirements than CPU-based hosting.
A few practical guidelines when evaluating providers across both layers:
- Request a trial period on Self-Hosted N8N VPS Hosting before committing annually — webhook stability under real load is hard to judge from a spec sheet alone
- Ask any Web Hosting Company in India directly about DPDPA 2023 data residency guarantees in writing, not just verbally
- When comparing best GPU cloud hosting options, benchmark actual inference latency with your target model, not just theoretical VRAM numbers
- Confirm whether n8n VPS hosting India plans include managed OS patching, since unpatched servers are a common source of downtime for teams without dedicated DevOps staff
- Ask each best GPU cloud hosting shortlist candidate about spot-instance versus reserved pricing, since reserved capacity is usually the safer choice for a production support workload that cannot tolerate sudden preemption
- If budget allows, keep the workflow engine on Self-Hosted N8N VPS Hosting and the model on a Dedicated NVIDIA GPU Server from the same provider, since unified billing and support tends to simplify troubleshooting when something breaks across both layers
- Read renewal pricing carefully on both n8n VPS hosting India and best GPU cloud hosting contracts, since promotional first-year rates on GPU compute in particular can rise sharply on renewal
- Check whether the Web Hosting Company in India you are evaluating offers a migration path from Self-Hosted N8N VPS Hosting to a Dedicated NVIDIA GPU Server without a full re-platforming project, since this saves significant engineering time later
Businesses new to this decision often assume n8n VPS hosting India and best GPU cloud hosting are the same purchase. They are not. One hosts the orchestration logic; the other hosts the model doing the actual reasoning. Budget and evaluate them separately, even if you eventually buy both from the same Web Hosting Company in India.
A useful way to think about this split is to picture two invoices arriving each month: one for Self-Hosted N8N VPS Hosting covering the orchestration layer, and one for best GPU cloud hosting covering inference, if you have gone down the self-hosted model route at all. Businesses that keep these two decisions separate in planning tend to make clearer infrastructure choices than those who try to solve both with a single generic server. A Web Hosting Company in India that can clearly explain the difference between n8n VPS hosting India and best GPU cloud hosting during a sales conversation is usually a good sign that they actually understand the workload, rather than reselling generic compute under a new label. For teams still comparing best GPU cloud hosting shortlists, ask for a reference customer running a similar inference workload before signing an annual contract, since Dedicated NVIDIA GPU Server performance claims are far more convincing with a live example attached. A Dedicated NVIDIA GPU Server contract should also specify uptime SLA terms clearly, the same way n8n VPS hosting India contracts typically do for the orchestration layer, and any Web Hosting Company in India worth signing with should be transparent about both from the first conversation. Getting a fair best GPU cloud hosting quote in writing before onboarding avoids surprise charges later, and confirming Self-Hosted N8N VPS Hosting renewal terms at the same time keeps both sides of the budget predictable.
Frequently Asked Questions
What is an n8n AI agent?
An n8n AI agent is a workflow built inside n8n that uses a large language model to reason, call tools, retain memory, and take action, rather than following a single rigid automation path. For customer support, this means it can read a ticket, decide what the customer needs, and either resolve it directly or escalate with full context.
Do I need coding skills to build an n8n AI agent?
No. n8n’s visual builder allows most of the structure, triggers, tools, and output steps, to be assembled without code. Some workflows use a Code node for custom logic, but a functional n8n AI agent for basic support automation can be built entirely through the visual interface.
Should I self-host n8n or use the cloud version for an AI agent?
For customer support workloads processing personal data under DPDPA 2023, self-hosting on Self-Hosted N8N VPS Hosting gives full control over data residency and access, which many businesses prefer for their compliance posture even though DPDPA 2023 does not strictly mandate India-only storage. n8n Cloud remains a reasonable option for teams prioritizing speed over infrastructure control, though most teams researching n8n VPS hosting India eventually move to self-hosting once ticket volume or compliance requirements grow.
What infrastructure does an n8n AI agent need to run reliably?
At minimum, a VPS with dedicated CPU and NVMe storage running n8n itself, this is exactly what Self-Hosted N8N VPS Hosting is designed for. If it calls a self-hosted open-weight model instead of a hosted API, a Dedicated NVIDIA GPU Server is needed to keep inference latency low under concurrent support traffic. Teams researching n8n VPS hosting India options should prioritize providers offering strong data security and privacy practices aligned with DPDPA 2023, and should also confirm whether the same Web Hosting Company in India offers GPU tiers if self-hosted inference is on the roadmap.
How much does it cost to run an n8n AI agent for support?
A starter setup using n8n self-hosted with a pay-per-token LLM API typically costs between three thousand and eight thousand rupees a month. Growth-stage teams running multiple support channels through Self-Hosted N8N VPS Hosting typically spend between eight thousand and twenty thousand rupees monthly, scaling upward with ticket volume and model choice. Teams that eventually add a Dedicated NVIDIA GPU Server for self-hosted inference should expect costs to rise accordingly, since GPU compute is priced very differently from standard VPS resources.
Which is better for a support n8n AI agent – hosted API or self-hosted GPU inference?
It depends on volume and data sensitivity. A hosted API is simpler and cheaper at low volume, while a Dedicated NVIDIA GPU Server becomes more cost-effective once ticket volume is high enough that token costs on a hosted API start exceeding fixed GPU costs. Comparing best GPU cloud hosting providers directly against your projected monthly API spend is the clearest way to make this decision, since the crossover point varies by business and ticket volume, and pairing that GPU decision with the right n8n VPS hosting India plan for the orchestration layer completes the picture.
Is a Web Hosting Company in India necessary, or can I use an international provider?
For any n8n AI agent processing personal data of Indian customers, using a Web Hosting Company in India can simplify operational and support logistics, though DPDPA 2023 itself does not strictly mandate India-only data storage. An international provider can technically run the workflow, but businesses should still evaluate cross-border data transfer implications and their own risk tolerance, which is why many support teams still prefer n8n VPS hosting India as a practical default for this use case, and the same reasoning extends to best GPU cloud hosting choices whenever patient or customer PII passes through the inference layer as well. A Web Hosting Company in India offering both the VPS and GPU tiers under one contract, with a Dedicated NVIDIA GPU Server available on request, tends to be the simplest long-term arrangement.

Pritam Kumar is a DevOps Engineer at CloudMinister Technologies, where he manages a multi-datacenter fleet of 100+ servers and architects end-to-end CI/CD pipelines and infrastructure automation using Kubernetes, Terraform, and Ansible. He holds an AWS Certified DevOps Engineer Professional certification and has served as a Google Cloud Mentor, reflecting both hands-on cloud expertise and a track record of mentoring others in the field. His work spans disaster recovery architecture, security incident response, and hosting infrastructure across Proxmox, cPanel/WHM, and Linux systems. Notably, Pritam led the design of Cloud Kavach, a self-hosted DC/DR SaaS portal, and directed remediation efforts for large-scale hosting security incidents involving webshells and command-and-control malware. He brings this depth of real-world infrastructure and security experience to the technical content he writes.